When the Lie Has a Bibliography
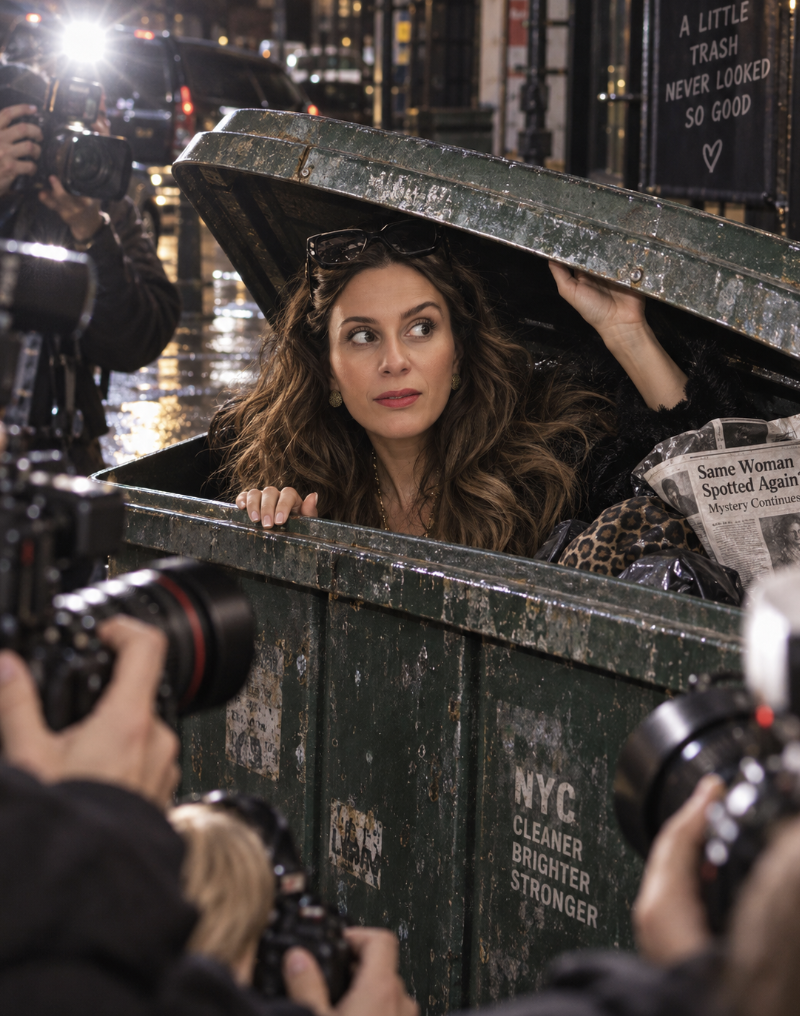
A lie used to become dangerous when enough people believed it. Now it can become dangerous when enough machines cite it.
A few weeks ago, I saw a woman telling a story online that I have not been able to stop thinking about.
She had gone on a podcast and the host asked her what it had been like growing up in Mexico. She had not grown up in Mexico. She assumed the host had simply made a mistake. Then she went to another event and somebody asked what it had been like teaching herself to code in Guadalajara. That was harder to dismiss. She had never even been to Guadalajara. So she Googled herself.
Google’s AI summary had apparently constructed an alternative biography for her. It said she was from Guadalajara. She suspected it had confused her with another woman online with a similar name and professional background who actually was from Mexico. That is already a fairly conventional AI hallucination. What happened next is not.
AI-generated articles began appearing about her that repeated the information from the AI summary. Those pages were indexed, and now, when the AI said she was from Guadalajara, it could cite sources proving it. The hallucination had escaped the model and entered the evidence base.
As she explained it, the AI was no longer simply hallucinating that she was from Guadalajara. It was confidently saying she was from Guadalajara and citing a source that said so. The mistake had become so convincing that eventually her own mother called to ask when she had taken her to Mexico.
There is another detail about this story that feels almost too perfect. The original post became difficult to find after the story exploded online. I only managed to recover the story because someone else had reposted it on LinkedIn, where the transcript was still indexed. Even the evidence of the false evidence needed an archive.
We have spent years discussing AI hallucinations as if they were temporary failures inside a model. The machine says something stupid, someone notices, we correct it, and we move on. But the internet gives hallucinations somewhere to live.
Once an invented fact becomes a webpage, a profile, a blog post, an automatically generated article or a database entry, future systems can retrieve it. The important shift is not simply from hallucination to publication. It is from publication to apparent evidence. Once the falsehood is indexed, retrieved and cited, repetition starts to resemble corroboration.
Ten websites saying the same thing are not necessarily ten sources. They may be ten descendants of the same mistake. That distinction matters because one of our proposed solutions to unreliable AI has been citations. We tell the machines to show their work, give us sources, link to evidence. That is an improvement, but a citation answers a much narrower question than we sometimes pretend. It can tell us where a statement came from. It cannot tell us whether the statement is true. A model can cite something perfectly and still be completely wrong.
I am no stranger to having lies written about me on the internet. For most of my life, though, I thought of that as a fairly unusual occupational hazard. It happened if you were public, somewhat famous, a political candidate, a CEO, an activist, or simply visible enough that strangers developed an interest in you.
In my own case, the volume increased dramatically as I became more public. In 2022 I was selected for the Obama Foundation’s Leaders Europe program, and when President Obama came to Copenhagen, I was chosen to introduce him before his speech at the Copenhagen Democracy Summit. That kind of visibility changes the amount of information produced about you. Some of it is correct, some of it is sloppy, some of it is interpretation, and much of it is simply not true.
Lies online take a toll. But if you have lived publicly for long enough, something slightly strange happens: you become desensitized. You learn that correcting everything is impossible. You stop assuming that because something has been published, it deserves an answer. You also learn that publication does not equal truth.
Eventually your family learns it too. By now, when members of my family read something about me online, their first instinct is often skepticism. Sometimes they know immediately that something cannot be true simply because they know where I was, what I was doing, who I was working with or what I actually said.
That is a strange kind of literacy to develop as a family. Most people have never had to develop it. Their parents have never had to wonder whether an article about their daughter is fabricated. Their partner has never had to ask whether the biography they just found is real. Their children have never needed to understand that the person described online and the person sitting across from them at the dinner table may occasionally be two very different people. Until now, most people have had no reason to prepare themselves for that experience.
That is what changes when fabrication no longer requires a human being to care enough to fabricate. You no longer need to be famous enough for another person to bother inventing something about you. A machine can confuse you with somebody else, invent a childhood, move you to another country, give you a degree you never earned, a company you never worked for, a political opinion you never expressed or a career you never had. Another system can turn that mistake into an article, another can index it, and another can cite it.
The information system can make a mistake and then begin using its own mistake as evidence. The false public identity used to be largely an occupational hazard of visibility. Now potentially everyone has one.
There is one thing I have learned from years of seeing inaccurate things written about me online that may become useful to everyone else: primary sources matter more than they used to.
There are claims about me online that are categorically false. Sometimes I am fortunate enough to be able to demonstrate that relatively easily, not because I can insist more loudly that they are false, but because an original record exists. A speech shows what I actually said. An organization can document what role I actually held. A company record shows what I actually worked on. A video shows what actually happened. The source existed before someone else wrote their interpretation of it.
That distinction becomes much more important in an information environment where repetition can masquerade as confirmation. A hundred secondary pages may all repeat the same claim, but the most important question is still whether there is anything underneath them that predates the claim itself.
This is why I increasingly think radical transparency may become a form of digital self-defense. Keep the original. Publish the speech. Document the project. Preserve the title. Keep the video. Make it possible for humans and machines to trace a claim back to something that existed before the internet began repeating itself.
That can solve some problems, but it also creates an extraordinary and deeply unfair burden. A machine can invent something about you in seconds. Correcting it may require years of documentation. The falsehood can propagate automatically while the truth may require an archive. And the burden falls on the person who was misrepresented.
You have to prove where you worked, what you said, what title you held, and where you lived. Sometimes, absurdly, you may even be expected to prove that something never happened at all.
We should not have to maintain public evidence lockers of our own lives simply because information systems might one day invent alternative versions of us. But this is where the conversation about AI and truth needs to go next.
The important question is no longer simply whether an answer has citations. We need to know where the claim originated, whether the sources are genuinely independent, whether they predate the claim, whether anyone verified them and whether there is a primary source underneath any of it.
Because the next information crisis may not look like fake news. It may look researched. The prose will be polished, the search results will agree, the answer will sound certain, and the footnotes will be there.
And the lie will have a bibliography.
References
The account of the woman falsely described by Google’s AI as having grown up in Guadalajara is preserved in a LinkedIn repost by Cameron Turner. In the video transcript, she explains that Google’s AI summary had attributed a Mexican background to her, that AI-generated articles subsequently repeated the claim, and that the AI summary then began citing those articles as evidence. The original post appears to have been removed or become difficult to access, but the repost and transcript remain indexed.
Cameron Turner’s LinkedIn repost and transcript: https://www.linkedin.com/posts/camjturner_ai-processimprovement-governance-activity-7497586593373974528-6fjl?utm_source=chatgpt.com
Ensayos relacionados
- IA y sociedad · 16 de agosto de 2026La IA devoró internet. Ahora queremos que decida quién es humanoLa marca de agua pretende hacer visible el contenido sintético. También podría convertir a las empresas de IA en quienes certifiquen la autoría humana.
- IA y sociedad · 8 de septiembre de 2026Elon Musk compró la propiedad equivocada para la aplicación de todoMusk compró Twitter para construir la aplicación de todo. Pero mientras él acumulaba atención, OpenAI acumulaba intenciones, y esa puede ser la dirección más valiosa de internet.
- IA y edtech · 18 de julio de 2026Si veo a alguien más vendiendo “PedTech”, voy a vomitarLa pedagogía nunca fue la idea que faltaba. Lo difícil era construir un sector cuya economía permitiera que la pedagogía siguiera en el centro cuando llegaba el dinero de los inversores.